Spatial Psychoacoustics
- You hear the position of a sound with just two ears. Everything on this page explains how.
- Left or right? The near ear hears the sound a fraction of a millisecond earlier (ITD) and a little louder (ILD). Timing works best for low sounds, level for high sounds: that split is the duplex theory.
- Up, down, front or back? The folds of your outer ear colour the sound differently for each direction. That colouring is described by the HRTF.
- Still unsure? Some directions give identical timing and level (the cone of confusion). A small turn of the head settles it.
- In a room, the first sound to arrive sets the direction (the precedence effect), and the amount of reverberation tells you how far the source is.
- No maths is needed to follow the ideas. Each section starts with something you can picture or try, and the equations come afterwards for those who want the numbers. Key terms are defined in the Glossary.
The Introduction made a promise: every spatial audio system, from a humble stereo pair to a 64-channel dome, is in the end a machine for fooling two eardrums. This page details this fact. Everything that follows in the guide, every panning law, every microphone array, every binaural filter, is an attempt to recreate the clues described here. Understand how we hear space and you understand why the techniques work, not merely that they work.
The page takes one clue at a time. Each starts with an everyday picture or a small experiment you can do yourself, then explains what is happening in plain words. Only then comes the equation, with each symbol explained, and a worked number you can check on a calculator. If you skip every equation you will still come away with the whole story.
The problem the brain solves
From the smallest sound, a leaf brushing the ground behind you, to a full orchestra spread across a stage, every source reaches you from somewhere in the space around you. Your auditory system assigns each sound a direction and a distance, separates overlapping sources, and keeps track of them as you turn your head.
Close your eyes and ask someone to snap their fingers at different places around you: in front, to the side, behind, above. Point to each snap. You will be right almost every time to the left and right, a little less often up and down, and now and then you will confuse front and back. By the end of this page you will know why.
What makes this remarkable is how little your brain has to work with. It never sees the sources. All it receives is two vibrations, one at each eardrum: two streams of air pressure changing over time. Imagine being handed two microphone recordings of a busy street and being asked to draw a map of where every car, voice and bird is. That is the job your brain does continuously, without effort.
This is an inverse problem with far more unknowns than measurements. To place one source you need three numbers: how far round it is (its azimuth, the left to right angle), how high it is (its elevation) and how far away it is (its distance). With many sources at once there are many such triples to find, and they all arrive mixed into the same two signals.
For readers who like to see it written down, call and the pressure at the left and right eardrum. Each source travels to each ear and is altered on the way: delayed, made quieter, its tone changed by the head and ear. That alteration is described by a filter, for the left ear and for the right, and depends on where the source is. The ear receives the sum of all the filtered sources:
The sign, convolution, simply means “passed through this filter”, and means “added up over all sources”. The brain only ever has and ; it has to work back to the sources and their positions.
Why it is possible at all. The two ear signals are not independent. They are two views of the same world, taken by two sensors about a head's width apart, with the head in between. That set-up leaves a handful of tell-tale clues, called cues:
- the difference in arrival time between the two ears says how far to the left or right a sound is;
- the difference in loudness between the two ears says the same thing, for high-pitched sounds;
- the change in tone caused by the shape of the outer ear says whether the sound is high or low, in front or behind;
- the balance between direct sound and room echo, together with loudness, says how far away it is.
Over a lifetime of listening, the brain has learned how these cues behave for its own head and ears, and it reads them back as positions.1
The rest of the chapter takes those cues one at a time: first the two that compare the ears (timing and level), then how they share the work, then the outer ear, then the ambiguities that remain and how we resolve them, and finally the cues for rooms and distance.
A word on directions. This chapter uses the frame set out in the Introduction, under Geometry of a position. Picture yourself at the centre of a clock lying flat around you. The azimuth is the angle round that clock: straight ahead, to your right, behind. The elevation is the angle upward from ear level, and the distance is measured from the centre of the head. The imaginary line running through both ear canals is called the interaural axis.
Interaural time difference (ITD)
What is happening. Your ears are about 18 cm apart. A sound coming from your right reaches the right ear first, then has to travel a little further, around the head, to reach the left ear. The delay is tiny, a fraction of a millisecond, but the brain measures it with astonishing precision. This interaural time difference, or ITD (“interaural” simply means “between the ears”), is the most reliable single clue for whether a sound is to the left or the right.
The bigger the angle, the longer the detour and the longer the delay. Straight ahead, the paths are equal and the ITD is zero. Fully to one side, the detour is as long as it gets.
In numbers. To put a figure on the delay, treat the head as a ball of radius , with an ear on each side. For a distant source, the extra distance the sound travels to the far ear has two parts: a straight run across the front of the head, and an arc as it wraps round the side. Dividing that extra distance by the speed of sound gives the delay. This is Woodworth's classic formula:2
Here is the azimuth in radians (one radian is about 57°), is a typical head radius and is the speed of sound at about 20 °C. The term is the straight run; the term is the arc round the head. The model is good enough for design work. Real heads give slightly larger delays for low-pitched sounds, because a sphere bends long waves differently from short ones.3

The largest possible delay. The ITD is greatest when the source is directly to one side, , or in radians:
That is about 660 microseconds, two-thirds of a millisecond: the ceiling for the human ITD.
No sound in open space can produce a larger delay between the ears, because no path round the head is longer. So if two speakers play the same signal more than about 0.66 ms apart, the image does not move further to the side; the brain starts to hear the late copy as a separate event, a point taken up again under the precedence effect.
How fine is our hearing of time? Listeners notice changes of roughly 10 microseconds near the front,4 a hundredth of a millisecond, and about one degree of azimuth. That is finer than the timing of any single nerve cell. The trick is teamwork: cells in the brainstem fire most strongly when signals from the two ears arrive at the same moment, and an array of such cells, each fed through a slightly different delay, works out which delay lines the two ears up.5
Worked example. How much delay does a source at produce? First convert the angle: rad, and . Then
A sound 30° to the right reaches the right ear about a quarter of a millisecond before the left. Notice how the delay grows quickly near the front and slowly near the side: moving a source from 0° to 30° adds 261 µs, but moving it from 60° to 90° adds much less. That is one reason we judge directions best straight ahead.

Where timing stops working. For a steady tone, the brain compares the wave peaks arriving at each ear. For a low tone the peaks are far apart, so it is obvious which peak in the left ear goes with which in the right. For a high tone the peaks come so quickly that several of them fit inside the delay, and the brain can no longer tell which peak matches which. It is like watching two sets of fence posts fly past a train window: if the posts are far apart you can tell which way one set is shifted against the other, if they are close together you cannot.
In numbers, the matching is safe while the delay is less than half the time between two peaks (half a period). With the maximum delay of 0.66 ms, that limit is reached at , and the confusion becomes serious around 1.5 kHz, where the wavelength approaches the size of the head. Above that, timing in the fine detail of the wave fails. The brain can still compare the timing of the slower rises and falls in loudness of a high sound (its envelope),6 but the main clue for high sounds is a different one, the subject of the next section.
Interaural level difference (ILD)
What is happening. Your head is in the way. A sound coming from your right reaches the right ear directly, while the left ear, hidden behind the head, hears it more quietly. This difference in loudness between the ears is the interaural level difference, or ILD.
The head only blocks high-pitched sounds, whose waves are small. Low-pitched sounds have waves several metres long that simply flow around the head, so both ears hear them at almost the same level. It is like waves on a lake meeting a post: small ripples stop behind it, a big swell rolls straight past. The ILD is therefore small for low sounds and large for high ones.
In numbers. What matters is the size of the head compared with the wavelength of the sound. Acousticians measure this with the number , where is the head radius. When is much smaller than 1, the wave is much bigger than the head and there is no shadow. When reaches about 1, the shadow starts to form. Since for a sound of frequency , the point falls at
So the head shadow starts to matter a little above 600 Hz, and becomes strong a few kilohertz higher. A rough model for a distant source is
where is the largest level difference at that frequency, reached when the source is fully to the side (). Measured on real heads, climbs from a fraction of a decibel at 200 Hz to roughly 5 to 8 dB at 1 kHz and up to about 20 dB above 5 to 10 kHz.78 For scale, 6 dB is roughly half the sound pressure, and 20 dB a tenth.
Why it takes over in the highs. Timing becomes ambiguous above about 1.5 kHz, and that is exactly where the head shadow has become strong. Level takes over where timing fails. The two cues share the frequency range between them, and this division of labour shapes the whole of our hearing of left and right.
Worked example. Take a 6 kHz tone at , with dB. Then : the right ear receives a signal more than 17 dB louder, about times the pressure. A 300 Hz tone at the same angle, with of perhaps 1 to 2 dB, gives under 2 dB, almost nothing. For low sounds the brain has to rely on timing instead. This frequency split is the single most important fact about hearing left and right, and it has a name.
The duplex theory and the 1.5 kHz crossover
The idea. Around 1907, Lord Rayleigh put the two cues together in what is now called the duplex theory (“duplex” meaning “two-part”): to tell left from right, we use timing for low sounds and level for high sounds, with a hand-over region in between.9 Each cue covers the range where the physics makes it reliable, and the brain leans on whichever one is available.
Think of two night-watchmen sharing a shift: one is reliable until midnight, the other from about 2 a.m. Between the two, neither is fully awake.
Why the hand-over sits near 1.5 kHz. Both limits come from the same thing: the size of the head.
- Timing works while the sound's waves are long compared with the path round the head. It starts to fail as the wavelength shrinks toward that path, around 1.3 to 1.5 kHz.
- Level needs waves comparable to or smaller than the head (). The shadow begins around 600 Hz and gives clear level differences by 1 to 2 kHz.
The two ranges meet in a band centred near 1.5 kHz. A quick check: a sound whose wavelength equals the distance between the ears, , has a frequency of
while the half-period limit for timing gave about 760 Hz. The real hand-over in human hearing lies between the two, near 1.5 kHz.

The band from about 1.5 to 3 kHz is the worst for telling left from right: timing has become unreliable and level is not yet at full strength. Localisation is measurably blurriest there. Keep it in mind when reading Stereo and Amplitude Panning: panning laws rely on whichever cue dominates in the frequency range of the signal.
Worked example: both cues at once. A sharp click contains low and high frequencies together. Place it at . Its low part, say around 500 Hz, carries a delay of . Its high part, say around 8 kHz, carries an ILD of about dB. Both point to the same place, 25° to the right, and because they agree, the image is sharp and stable. When an audio system makes them disagree, for instance a level difference pointing one way and a delay pointing the other, the listener hears a blurred, unstable image, or one stuck inside the head: a failure every spatial audio engineer learns to recognise.
Spectral cues and the pinna: the HRTF
What is happening. Timing and level differences place a sound on the left to right line, but they say almost nothing about height, or about front versus back. A source 30° above and one 30° below, on the same side, give nearly identical differences between the ears. Something else must tell them apart, and that something is the shape of your outer ear, the pinna.
The folds of the pinna, along with the head and shoulders, act like a set of tiny reflectors. Before entering the ear canal, part of the sound bounces off these folds and arrives a split-second after the rest. The two copies interfere, boosting some frequencies and cancelling others. Crucially, the pattern changes with direction: a sound from above is coloured differently from one in front or behind. The brain has learned to read that colouring, the sound's tonal fingerprint, as height and as front or back.
The Head-Related Transfer Function. The full effect of head, ears and shoulders on a sound coming from a given direction is captured by the Head-Related Transfer Function (HRTF), one for each ear. You can think of it as an equaliser setting that depends on direction: for every direction, it says how much each frequency is boosted or cut, and how much it is delayed, on its way to each eardrum. Written out, it compares the sound at the eardrum with the sound that would be at the centre of the head if the head were not there:
where and describe the sound at each ear, frequency by frequency, and the sound at the centre of the head with the head absent.
The HRTF is the basis of binaural audio over headphones: filter a dry recording through the HRTF of a given direction, play it through headphones, and the listener hears it coming from that direction. This is introduced in Two paths to the ears and covered in Binaural.10 The HRTF is not a separate cue from timing and level: it contains them, since comparing the left and right HRTFs gives the ITD and the ILD. What it adds is the tonal colouring at each ear, the pattern of peaks and dips imposed by the pinna.
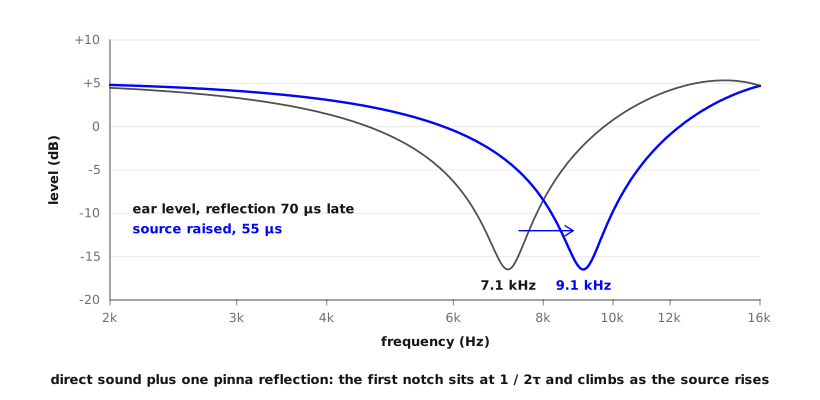
Height from a moving dip. The most important feature of that colouring is a sharp dip, or notch, somewhere between 5 and 12 kHz, whose frequency rises as the source rises.11 It comes from the interference just described: the direct sound and a copy reflected off a fold of the pinna cancel each other at certain frequencies.12 If the reflection arrives a time after the direct sound, the cancellations fall at
As the source moves up or down, the reflection path changes, changes, and the notch slides. The brain reads, in effect, “dip near 7 kHz, so the source is roughly at ear level”, and so on. Because these features live above 5 kHz, judging height needs high frequencies: a low hum or a muffled sound is hard to place vertically.
Front and back. The pinna faces forward, a little like a cupped hand. Sounds from behind are slightly duller and carry their own dip pattern. This is a weak cue, easily fooled, which is why front and back mix-ups are common.
Everyone's ears are different. Here is the catch for audio engineering. Pinna shapes are as individual as fingerprints, so the exact positions of the peaks and dips differ from one person to the next.
Listening through someone else's HRTF, for instance a standard set measured on a dummy head, makes height less precise, multiplies front and back mix-ups, and tends to pull sounds inside the head.13 DAM Audio's binaural engine, BSE, is built to sidestep this problem: instead of playing sound through a measured HRTF set, it models these mechanisms directly.
Personalising HRTFs remains an open problem in binaural audio, treated in depth in Binaural.
Worked example. Suppose that, for a source at ear level, a pinna reflection arrives after the direct sound. The first notch sits at . When the source rises and the reflection delay shortens to , the notch climbs to about 9.1 kHz. The brain reads that 2 kHz upward slide as “higher”, without needing the other ear at all. That is why someone with one ear blocked can still judge height fairly well, while being nearly unable to tell left from right.
The cone of confusion
What is happening. Your ears sit on the sides of your head, so they hear front and back the same way. A sound a little in front of you on the right, and its mirror image a little behind you on the right, reach the two ears with the same delay and the same level difference. So do a sound a little above and one a little below. Timing and level alone cannot tell them apart. All the directions that give the same clues form a cone pointing sideways out of your ear: the cone of confusion.
In numbers. Call the angle between the source and the line through the ears. Since the ITD depends only on this angle, every direction with the same gives the same delay:
This is the same Woodworth formula as before, measured from the ear line instead of from the nose. A given delay picks out a given : a whole cone of directions, not a single point.

How the brain gets out of it. Two mechanisms come to the rescue.
- The ear's colouring. The pinna dips of the previous section differ between front and back and between high and low, even when timing and level are identical. They collapse the cone to a single direction, provided the sound has enough high frequencies and the listener is using their own ears. With someone else's HRTF, the cone comes back and front and back mix-ups multiply.
- Moving the head. This is the elegant one, first analysed by Wallach.14 Turn your head a few degrees to the right. A source in front of you moves toward the centre of your view, and its delay shrinks. A source behind you moves further to the side, and its delay grows. The same small turn makes the two change in opposite directions, so the brain instantly knows which one it is hearing. It does this all the time, without you noticing, by comparing its own movement with how the cues change.
Worked example. A source at and its mirror image behind at both give 261 µs. Turn the head 10° to the right. The front source is now 20° off the nose, and its ITD drops to about 176 µs. The rear source is now 40° from straight behind, and its ITD rises to about 342 µs. A 10° turn opens a gap of more than 150 µs, fifteen times the smallest delay we can notice, and the ambiguity is gone.

This is why head tracking transforms binaural audio. Without it, the sound turns with your head, the cues never change, and listeners stay stuck on the cone of confusion. With it, the sound stays put while you move, and they can use the very mechanism evolution gave them. The point returns throughout Binaural and Transaural; on loudspeakers, crosstalk cancellation such as XTC delivers the same ear signals without headphones.
The precedence effect (Haas)
What is happening. Real rooms are full of reflections. Within a few milliseconds of the direct sound, dozens of delayed, quieter copies arrive from the walls, floor and ceiling, each from its own direction. If we located every copy, every word spoken in a room would seem to come from everywhere at once. It does not, thanks to the precedence effect, also called the law of the first wavefront or the Haas effect (see the Glossary): a sound and the copies arriving shortly after it are merged into one event, heard where the first one came from. The later copies only add loudness and a sense of space.15
The brain is, in effect, trusting the first messenger. The first arrival has necessarily travelled the shortest path, the straight line from the source, so it is the one that tells the truth about direction.
How it depends on the delay. Imagine a sound followed by a single copy of itself, delayed by .
- Under about 1 ms: the two blend, and the sound seems to come from somewhere between the two positions. This is summing localisation, and it is how stereo works: two loudspeakers playing slightly different versions of a signal add up to one phantom image between them, as Stereo and Amplitude Panning explain.
- From about 1 ms to 5 to 10 ms: still one sound, but now its position is set by the first arrival. The copy can be considerably louder, by up to about 10 to 12 dB, and the listener still points toward the first one.16 The copy changes the tone and loudness, not the direction.
- Beyond about 30 to 40 ms: the copy breaks away and is heard as a separate echo, with its own position. The limit is not sharp: clicks and other sharp sounds break away sooner than sustained sounds.17
For readers who want it as a formula: if the first arrival points to a direction and the copy to , the perceived direction is roughly a weighted average,
where the weight is about when both blend (under 1 ms), and climbs toward 1 in the precedence window, when the first arrival wins.

Worked example: Haas's classic experiment. A person speaks in front of you; a loudspeaker off to the side plays the same speech 15 ms later. For the loudspeaker to pull the voice toward itself, it has to be about 10 dB louder than the talker, and even then the pull is only partial. Below that level, listeners hear the voice coming from the talker, even though the loudspeaker is plainly audible.
Concert and conference sound systems rely on this every day. Speakers placed further back in a hall are delayed so that their sound arrives just after the sound from the stage. The audience hears the voice coming from the stage, while the nearby speakers quietly supply most of the volume. Reflections arriving after the precedence window bring echo, colouration and the sense of a space, the topics of Reverberation and Direct, Diffuse & Envelopment.
Why it matters here. The precedence effect is the bridge between the clean cues described above and the messy reality of rooms. It is why one correct first arrival survives a storm of reflections, and why spatial systems can place a sound even in very reverberant venues.
It also sets a hard rule for systems with several loudspeakers: get the timing of the first arrival right, or no amount of level adjustment will fix where people hear the sound.
Distance perception
Direction gives two of the three numbers we need; the third is how far. Picture someone walking away from you across a large hall: their voice gets quieter, but it also sounds more and more “roomy”, as if more of it came from the walls than from the person. Distance is the hardest of the three to judge, because no single clue translates neatly into metres. The brain combines several: how loud the sound is, how much of it comes straight from the source compared with from the room, how dull it sounds, and, very close up, how the wave is shaped.18 None is reliable alone; together they give a usable, if rough, sense of depth. This section is an introduction; Distance & Air treats the subject in full.
Loudness. In open space, a sound gets quieter with distance in a very regular way: each time the distance doubles, the sound pressure halves, which is a drop of 6 dB. In equation form, the pressure falls in proportion to , and the level difference between two distances and is
Doubling the distance gives dB: the familiar −6 dB per doubling of distance. But loudness on its own is misleading: a quiet sound nearby and a loud one far away can reach the ear at the same level. The brain only turns loudness into distance when it knows roughly how loud the source should be. A whisper is quiet by nature; a shout is not.
Direct sound against room sound. In a room, you hear two things: the direct sound, coming straight from the source, and the reverberation, the sound that has bounced around the room many times. The direct sound gets quieter as the source moves away, following the 6 dB rule. The reverberation, on the other hand, fills the whole room at roughly the same level everywhere. So as a source moves away, the direct part shrinks while the room part stays the same, and the balance between them, the direct-to-reverberant ratio or DRR, falls steadily:
where stands for the energy of each part. Because the room part is set by the room, not by the source, the DRR does not require knowing how loud the source “should” be: it is a much more dependable distance clue than loudness.19 This is why a dry recording sounds close and the same recording with plenty of reverb sounds far away, and why the reverb send is a mix engineer's main depth control. Reverberation goes further.

Duller with distance, and the gap before the first echo. Over long distances, the air itself absorbs high frequencies more than low ones, a few decibels per 100 m at 4 kHz and more above,20 so a distant source sounds duller, like thunder rumbling far away compared with a nearby crack. The brain uses this as a weak distance clue. Another hint is the short silence between the direct sound and the first strong reflection: it shrinks as a source moves away from you toward a wall.
We squeeze distances together. How far a sound seems is not the same as how far it is. Pooling many studies, Zahorik and colleagues found that perceived distance follows a so-called power law of the real distance :21
The exponent being smaller than 1 means that large distances are squeezed together.
Listeners overestimate near distances and underestimate far ones, pulling the whole world of sound toward a comfortable middle distance.
A worked case, with and : a source at m is heard at m; one at 9 m is heard at m. The two are five metres apart in reality but only one metre apart to the ear. Systems that try to render a wide range of distances have to live with this. Conveying that one source is farther than another is far easier than conveying how many metres away it is.

Resolution limits: how fine is our hearing?
Every clue has its limits of precision. Together they set how sharp our hearing of space is, and therefore how precise a reproduction system needs to be. There is no point in being more precise than the ear, and no excuse for being less.
Minimum audible angle (MAA). This is the smallest movement of a sound that a listener can reliably notice. It is best straight ahead, about 1° for a sound rich in frequencies, and gets worse toward the sides, reaching 10° or more at .22 We saw why with the ITD: near the front, a small turn changes the delay a lot; near the side, a small turn changes it very little. In terms of the Woodworth formula, the rate of change of is , which equals 2 straight ahead and only 1 at the side. The MAA is also worse in the blind spot between 1.5 and 3 kHz, exactly as the duplex theory predicts.
Smallest noticeable changes. The smallest change a listener can detect is called a just-noticeable difference, or JND. For the two ear-comparison cues they are remarkably small:
- Timing (ITD): about 10 to 20 microseconds near the front, a little more toward the sides, out of a range of 660 µs.4
- Level (ILD): roughly 0.5 to 1 dB, out of a range of up to about 20 dB in the highs.23
These figures fit together neatly. Near the front, the ITD changes by per radian, or about per degree. A 10 µs JND therefore corresponds to about , in close agreement with the measured MAA of about 1°. The geometry of the head and the precision of the brain together predict how well we hear.
The table sums up the clues.
| Cue | What it is | Works best for | Range | Smallest noticeable change | Tells you |
|---|---|---|---|---|---|
| ITD | Difference in arrival time between the ears | sounds below about 1.5 kHz | 0 to 660 µs | about 10 µs in front | Left or right |
| ILD | Difference in level between the ears | sounds above about 1.5 kHz | 0 to 20 dB | 0.5 to 1 dB | Left or right |
| Pinna colouring (HRTF) | Peaks and dips at each ear | sounds above about 5 kHz | dip moves from 5 to 12 kHz | differs per person | Up or down, front or back |
| Head movement | How the cues change when you turn | all sounds | Resolves the cone of confusion | ||
| Precedence | Which arrival comes first | all sounds | merging up to 30 to 40 ms | echo threshold | Direction in rooms |
| Loudness and DRR | Level, direct against room sound | all sounds | depends on the room | several dB | Distance |
Implications for spatial system design
Pulling the threads together: how we hear dictates how spatial audio must be engineered. A spatial audio system succeeds exactly as far as it delivers consistent, correct versions of these clues to the two eardrums.24
- Left and right need the right clue in the right range. Below about 1.5 kHz, get the timing between the ears right; above it, the level. Stereo and amplitude panning create level differences between loudspeakers that turn into the right clues at the ears; Ambisonics rebuilds a sound field that gives approximately the right clues in a central listening area; wave field synthesis, as in DAM Audio's WFS-X, rebuilds the waves themselves so the clues hold over a whole area. Whatever the method, the split of the duplex theory is the yardstick.
- Consistency is everything. When timing and level disagree, or a generic HRTF imposes the wrong dips, the image blurs, collapses into the head or jumps from front to back. Much of the craft of binaural and transaural rendering is keeping every clue in agreement with every other.
- Height and front or back are fragile. They live in the high frequencies coloured by the pinna, and in head movement. Systems that ignore individual ears or leave out head tracking give up accuracy in height and invite front and back confusion: the cone of confusion is what you get by default.
- The first arrival wins. Because of the precedence effect, the timing of the direct sound decides where people hear it, even among reflections. Systems with many loudspeakers must be time-aligned so that the intended source arrives first. Reflections can then do their proper job: conveying distance, room and envelopment.
- Distance is squeezed and has few clues. Use the balance of direct and reverberant sound as the main depth tool, expect perception to compress your range, and do not rely on loudness alone.
- Match the system's precision to the ear. There is no point in setting delays to the nanosecond when the ear notices about 10 µs, and no excuse for a 1 dB level error in the highs when that is close to what the ear notices. The limits of hearing show where the engineering effort should go.
Every technique in Part II is, at heart, a different strategy for delivering these clues, and every limitation you will meet, a small sweet spot, a change of tone, front and back mix-ups, traces back to a clue the method approximates rather than reproduces. With the workings of hearing in hand, the next chapter, Multichannel & Immersive Formats, turns to the formats that carry these clues from production to playback.
References
Books
- Blauert, J. (1997). Spatial Hearing: The Psychophysics of Human Sound Localization (rev. ed.). MIT Press.
- Woodworth, R. S. (1938). Experimental Psychology. Henry Holt.
- Moore, B. C. J. (2012). An Introduction to the Psychology of Hearing (6th ed.). Brill.
Interaural cues
- Rayleigh, Lord (1907). “On our perception of sound direction.” Philosophical Magazine, 13(74), 214–232.
- Jeffress, L. A. (1948). “A place theory of sound localization.” Journal of Comparative and Physiological Psychology, 41, 35–39.
- Klumpp, R. G., & Eady, H. R. (1956). “Some measurements of interaural time difference thresholds.” JASA, 28(5), 859–860.
- Feddersen, W. E., Sandel, T. T., Teas, D. C., & Jeffress, L. A. (1957). “Localization of high-frequency tones.” JASA, 29(9), 988–991.
- Mills, A. W. (1958). “On the minimum audible angle.” JASA, 30(4), 237–246.
- Mills, A. W. (1960). “Lateralization of high-frequency tones.” JASA, 32(1), 132–134.
- Henning, G. B. (1974). “Detectability of interaural delay in high-frequency complex waveforms.” JASA, 55(1), 84–90.
- Shaw, E. A. G. (1974). “Transformation of sound pressure level from the free field to the eardrum in the horizontal plane.” JASA, 56(6), 1848–1861.
- Kuhn, G. F. (1977). “Model for the interaural time differences in the azimuthal plane.” JASA, 62(1), 157–167.
Pinna and HRTF
- Batteau, D. W. (1967). “The role of the pinna in human localization.” Proceedings of the Royal Society B, 168, 158–180.
- Hebrank, J., & Wright, D. (1974). “Spectral cues used in the localization of sound sources on the median plane.” JASA, 56(6), 1829–1834.
- Wightman, F. L., & Kistler, D. J. (1989). “Headphone simulation of free-field listening. I and II.” JASA, 85(2), 858–878.
- Middlebrooks, J. C., & Green, D. M. (1991). “Sound localization by human listeners.” Annual Review of Psychology, 42, 135–159.
- Wenzel, E. M., Arruda, M., Kistler, D. J., & Wightman, F. L. (1993). “Localization using nonindividualized head-related transfer functions.” JASA, 94(1), 111–123.
Head movement and precedence
- Wallach, H. (1940). “The role of head movements and vestibular and visual cues in sound localization.” Journal of Experimental Psychology, 27, 339–368.
- Wallach, H., Newman, E. B., & Rosenzweig, M. R. (1949). “The precedence effect in sound localization.” American Journal of Psychology, 62(3), 315–336.
- Haas, H. (1951). “Über den Einfluss eines Einfachechos auf die Hörsamkeit von Sprache.” Acustica, 1, 49–58.
- Litovsky, R. Y., Colburn, H. S., Yost, W. A., & Guzman, S. J. (1999). “The precedence effect.” JASA, 106(4), 1633–1654.
Distance
- Bronkhorst, A. W., & Houtgast, T. (1999). “Auditory distance perception in rooms.” Nature, 397, 517–520.
- Zahorik, P. (2002). “Assessing auditory distance perception using virtual acoustics.” JASA, 111(4), 1832–1846.
- Zahorik, P., Brungart, D. S., & Bronkhorst, A. W. (2005). “Auditory distance perception in humans: A summary of past and present research.” Acta Acustica united with Acustica, 91(3), 409–420.
Standards
- ISO 9613-1 (1993). Acoustics: Attenuation of sound during propagation outdoors. Part 1: Calculation of the absorption of sound by the atmosphere.